A collection system can have more devices and still complete no more useful work per hour. Some devices may be offline, some may not match a task’s requirements, and others may be waiting on preparation, control traffic, or evidence upload. Counting hardware alone hides these constraints.
The useful question is not simply how many Android devices are connected. It is how many eligible attempts the system can complete with interpretable evidence, at a predictable rate.
Capacity is a pipeline, not a fleet count
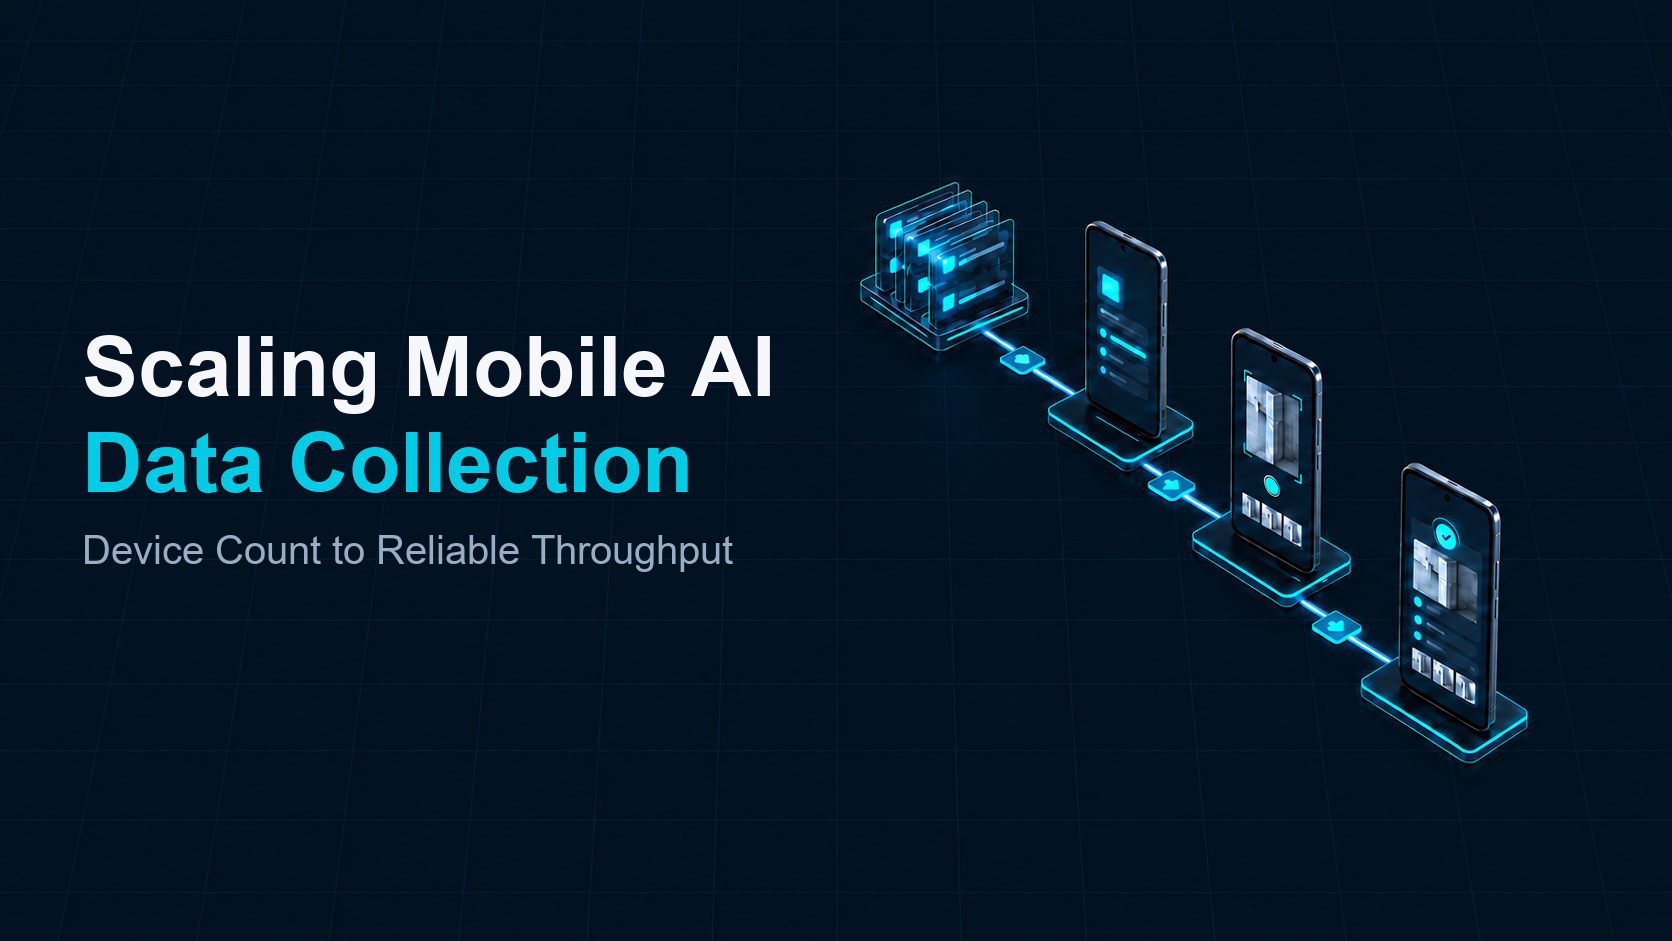
A physical-device run passes through several stages: a task enters the queue, a compatible device is selected, the device is prepared, work is delivered, execution is observed, and evidence is returned and assessed. Each stage has its own capacity and failure modes.
The system’s sustainable throughput is bounded by its slowest stage. Adding devices helps only when device execution is the bottleneck. If assignment is slow, devices sit idle. If evidence ingestion falls behind, completed runs accumulate without usable records. If preparation or recovery takes too long, nominal device count overstates the capacity available to the next task.
A rough planning model is:
usable throughput ≈ min(stage capacity) × eligible-device availability × evidence completion rate
This is a way to structure measurement, not a performance promise. The factors must be measured for the actual task mix and device environment. A short foreground interaction, a long stateful workflow, and a task that produces several screenshots do not consume the same resources.

Separate connected devices from eligible devices
A connected device is not automatically ready for every task. A task may require a particular Android version, app build, account state, network profile, or starting condition. Another device may be held out because a previous run ended in an uncertain state.
Keep these states distinct in scheduling and reporting:
- Registered: the system can identify the device.
- Reachable: its control channel is currently available.
- Eligible: it satisfies the task’s declared requirements.
- Ready: its relevant starting conditions have been prepared and checked.
- In use / recovering / held: its current lifecycle prevents another assignment.
These labels are an example vocabulary, not a required API schema. The important point is that “online” should not silently mean “safe to assign.” This distinction builds on the state-management question in Device State Management: The Overlooked Problem in Mobile AI Data Collection.
Schedule by task requirements and device constraints
At small scale, an operator can often choose a device by inspection. As the fleet grows, assignment needs explicit constraints. A task should declare what it needs; a device record should expose the attributes needed to decide whether it is a candidate.
A scheduler can then filter before ranking:
- Exclude devices that are unreachable, already occupied, or held for recovery.
- Keep only devices that match required OS, app, account, or network conditions.
- Prefer a suitable device using a documented policy, such as least recent use or an explicit test cohort.
- Reserve the device for one attempt and record the assignment.
- Release it only after the run’s evidence and end state have been handled.
This is not about maximizing parallelism at any cost. Physical interaction is stateful: two independent controllers cannot safely act on the same app session at once unless the environment provides isolation. For many UI tasks, one active attempt per device is the clearest default. Concurrency should increase across eligible devices, while any within-device concurrency is justified by an explicitly isolated workload.
Make retries safe to reason about
More devices create more opportunities for partial failures: a request can time out after reaching a device, a connection can drop during execution, or a result can be captured while upload is still pending. A retry policy that treats every timeout as “nothing happened” can duplicate an action or attach evidence to the wrong attempt.
Keep a parent task identifier and a distinct attempt identifier. Record the selected device, dispatch time, execution state, and evidence references against that attempt. If the outcome is uncertain, preserve it as uncertain until observation or recovery resolves it. Do not convert a transport failure directly into a task failure or a task success.
This continues the identity and evidence model described in How APIs Connect AI Data Pipelines to Physical Android Devices: a command response, a device execution, and a verified outcome are separate facts. A retry should create a traceable new attempt or an explicitly idempotent continuation—not overwrite the history of the first one.
Treat device preparation and recovery as capacity
A device spends time outside task execution. It may need an app launch, a baseline check, a state reset, a network change, or recovery after an incomplete run. These steps are part of the capacity model.
Measure how long devices wait between attempts and why they are unavailable. A high “connected” count combined with a low “ready” count may indicate a preparation bottleneck, state drift, or a recovery queue. Android’s test orchestration documentation illustrates a related trade-off: isolating tests and clearing app data can reduce shared state, while restarting the app adds execution time. The right preparation policy depends on the question being tested. AndroidJUnitRunner and Test Orchestrator
After evidence is secured, a run should leave the device in a known next state: restored for an independent attempt, preserved for an intentional sequence, or held until an operator or workflow resolves uncertainty. The state transition should be recorded before the scheduler makes the device eligible again.
Measure the queue and the evidence path
A fleet dashboard that shows only device count and CPU use will not explain where useful work is lost. Track the lifecycle end to end:
- queued work and queue-wait time;
- devices registered, reachable, eligible, ready, occupied, and held;
- assignment-to-dispatch delay and execution duration;
- retry counts and reasons, preparation time, and recovery time;
- evidence expected, captured, uploaded, and linked to an attempt;
- completed outcomes and unresolved or excluded attempts.
Look at distributions and trends, not only averages. A growing queue wait or rising tail latency can appear before overall completion rate falls. For each stage, pair volume with errors and latency; for queues, include both queue depth and time spent waiting. These are standard observability patterns for online and offline processing systems. Prometheus instrumentation practices
The goal is not to collect every possible metric. Choose signals that answer operational questions: Are tasks waiting for compatible devices? Are devices idle because assignment is slow? Are runs complete but evidence still pending? Are retries concentrated around one device or one preparation step?
Scale in measured stages
A practical expansion starts with a representative workload at the current fleet size. Establish a baseline for queue wait, ready-device availability, run duration, recovery time, retry rate, and evidence completion. Then add capacity in cohorts while keeping the task mix and acceptance criteria comparable.
At each stage, ask which resource became limiting. If devices are busy and the queue grows, more eligible capacity may help. If devices are idle while tasks wait, inspect matching and assignment. If execution finishes but evidence lags, improve the capture or ingestion path before adding more phones. If recovery time dominates, fix the end-of-run policy first.
This is the same capacity-planning principle used in distributed systems: scheduling depends on resource capacity and workload requirements, while monitoring must expose saturation and delay. A device fleet adds constraints that generic compute clusters do not—physical availability, app state, network context, and evidence tied to a real interaction—so the measurement model must include them. Kubernetes node capacity and scheduling provides a useful analogy for resource-aware placement, not a drop-in device scheduler.
Scale the evidence, not only the execution
Moving from 10 devices to 100 or more changes the volume of events, captures, and partial outcomes as much as it changes the number of endpoints. A dependable system preserves the relationship between task, attempt, device, conditions, and evidence even when work is queued, retried, or recovered.
The objective is not to make every device busy every second. It is to complete more comparable, interpretable runs without losing track of what happened. Device count is an input. Reliable throughput is the result.